AI-generated illustration. Evidence can justify a narrowly defined advisory role without granting authority to approve or release changes.
Evaluate an AI code review tool for a defined role, not for blanket adoption. Set repository-specific acceptance criteria before testing. External benchmarks can inform a shortlist, but they do not establish that a tool should approve changes, enforce your policies, or replace an accountable reviewer.
In its October 5 ReviewBench: An open benchmark for AI code review, GitHub describes a benchmark built on representative GitHub pull requests, multi-source ground truth, calibrated evaluation, and production-aligned metrics. These are publisher claims, not independently verified findings. The supplied excerpt does not provide enough information to assess benchmark quality, coverage, results, or tool rankings.
For engineering leaders, the adoption question is: What evidence would justify giving this tool this particular responsibility?
Separate comparison evidence from permission to act
Three kinds of evidence answer different questions:
- External benchmarks: How do systems compare under the benchmark’s conditions? Inspect task definitions, tool configurations, scoring rules, and limitations before using a result. The ReviewBench excerpt alone cannot answer those questions.
- Repository-specific evaluation: Does the proposed configuration find useful issues in your code, with acceptable misses and review overhead? Does it recognize your architecture and security requirements?
- Accountable judgment: Who decides whether a finding is valid, a fix is sufficient, and the remaining risk is acceptable?
Do not combine these into a single score. A useful defect detector is not necessarily an effective architecture-policy reviewer. Neither role automatically grants release authority.
Authorize the evaluated role, not the product as a whole.
Write an evidence-to-authority matrix first
Complete this matrix before demonstrations or comparisons. Replace the suggested owners with named people or established roles in your organization.
| Proposed reviewer role | Required evidence | Evaluation owner | Approval authority | Unresolved limitations | Reevaluation triggers |
|---|---|---|---|---|---|
| Advisory review of routine application changes | Locally adjudicated examples; missed-issue and false-alarm analysis; checks against applicable architecture and security policies | Repository maintainer | Engineering owner authorizes advisory use; existing code owners approve changes | Finite examples cannot establish defect absence; excluded change types remain unqualified | Material model, configuration, repository, or policy changes; recurring misses |
| Additional review input for authentication changes | Authentication-specific examples; designated security reviewer’s adjudication; checks against relevant trust boundaries and access-control requirements | Security reviewer with repository maintainer | Security lead authorizes assistive use; designated security approval remains required | Diff-only context may not establish system-wide behavior; clean output is not security approval | Authentication redesign, security-policy changes, new failure modes, or tool changes |
| Required review step before human approval | Evidence for relevant change classes; handling of errors, missing context, incomplete runs, and service outages | Engineering productivity owner with affected code owners | Governance owner authorizes workflow requirement; humans retain merge and exception authority | Completion proves the step ran, not that the change is safe | Workflow or permission changes; incomplete runs; increasing exception requests |
These are separate decisions, not a maturity ladder. A team can accept routine advisory review while declining authentication assistance or a required workflow role.
If review is a required step, an unavailable or incomplete result means no review evidence, not a clean review. Specify who may authorize an exception and how it is recorded.
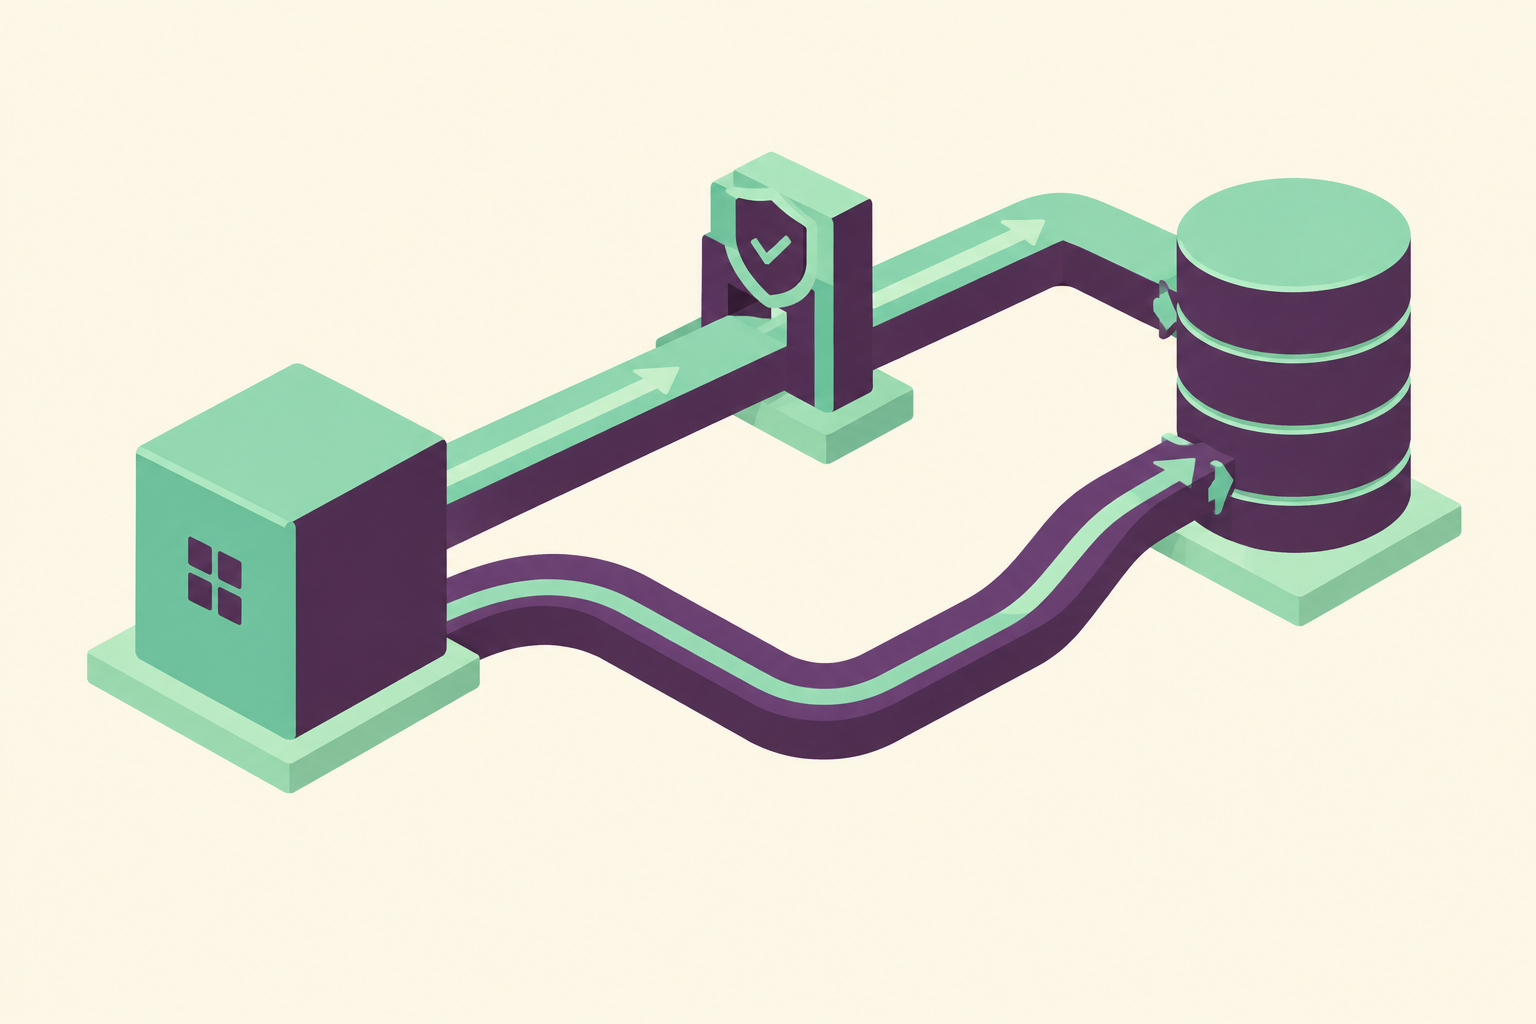
AI-generated illustration. An illustrative security-policy case: a protected operation has a path that bypasses authorization. Repository-specific evaluation should test such violations, not infer security competence from routine review success.
Define acceptance before testing
“Improve review quality” is not an acceptance criterion. It leaves room to redefine success after seeing the results.
Scope and policy expectations
Name the repositories, change classes, configuration, and context available to the tool. State exclusions explicitly.
Turn your policies into review cases. If your architecture policy prohibits direct access from a user-facing service to a restricted data store, include both a violating change and a compliant alternative. If your security policy requires authorization on every protected operation, include a case where one path bypasses that check.
These are illustrative policies. Use your actual rules and record which cases test each one.
Locally adjudicated examples
Use approved historical changes, isolated fixtures, or synthetic pull requests without live customer data or production credentials. Include known defects, compliant changes, and changes that could invite an incorrect warning.
A maintainer should establish expected findings, with security participation where relevant. Original review comments are not necessarily complete ground truth. Adjudicate unexpected findings too: a tool may identify a valid issue missing from the answer key.
Keep tuning examples separate from the acceptance set. Otherwise, the evaluation may show adaptation to familiar examples rather than performance on unseen changes.
Misses, false alarms, and incomplete evidence
Record:
- Known issues missed, by policy area and severity.
- Valid findings, including newly discovered issues after adjudication.
- Incorrect findings, with duplicates and non-actionable comments tracked separately.
- Human effort required to resolve the output.
- Cases the tool could not assess because context was missing or execution failed.
Report counts and denominators, not just an aggregate score. Never count an unevaluated case as a success. Set acceptable review burden against the capacity of the people investigating findings.
Worked example: routine advice does not qualify authentication review
Hypothetical example, not measured product performance: A team is considering two roles for the same tool. All examples are isolated fixtures, all findings are assumed to be locally adjudicated, and every fixture receives an assessable result.
Before evaluation, the team sets these criteria:
- Routine advisory scope: Twenty application changes contain eight known issues. No security- or architecture-blocking issue may be missed. At most one low-severity miss and three incorrect findings are acceptable across the set. This false-alarm allowance reflects the hypothetical team’s review capacity, not an industry standard.
- Authentication assistance scope: Ten authentication changes contain six known security-policy violations. Finding all six is necessary to pass this limited evaluation. Even a pass would authorize only assistance, not security approval.
- Both scopes: Every fixture must receive an assessable result. Failures or missing context require investigation, not a clean-review score.
Suppose the outcomes are:
| Scope | Assumed outcome | Authorization decision |
|---|---|---|
| Routine application changes | Seven of eight known issues found; sole miss is low severity; three incorrect findings; no blocking policy issue missed | Meets the stated criteria for advisory use in this scope |
| Authentication changes | Four of six known violations found; two authorization-policy violations missed | Does not qualify for authentication assistance |
Routine success does not offset authentication misses. A combined score would hide the boundary that matters to the decision.
The team can authorize routine advisory use while leaving authentication review with designated security reviewers. Before reevaluation, it should investigate whether the misses came from missing context, unclear policy representation, or another limitation. No explanation should be assumed without evidence.
The permission boundary is set before results arrive. The limits remain: small, curated sets do not establish production defect rates, and success on a finite evaluation does not establish the absence of defects.
Record a narrow, auditable adoption decision
The outcome should be an authorization record, not simply “pilot passed.”
Authorized role: [specific advisory or required-input role] for [repositories and change classes], using [evaluated configuration].
Evidence: [evaluation record], adjudicated by [owners], against [predeclared acceptance criteria].
Excluded scope: [change classes and policies not qualified].
Human authority: [roles] retain change approval, security approval, and exception decisions. An AI finding, or the absence of findings, does not constitute release approval.
Limitations and triggers: [known misses, context gaps, and events requiring reevaluation]. [Named owner] may suspend authorization if those limits are exceeded.
Keep it narrow: what the evidence supports, what it does not, and who remains responsible.
For a next step, explore OpenThunder.